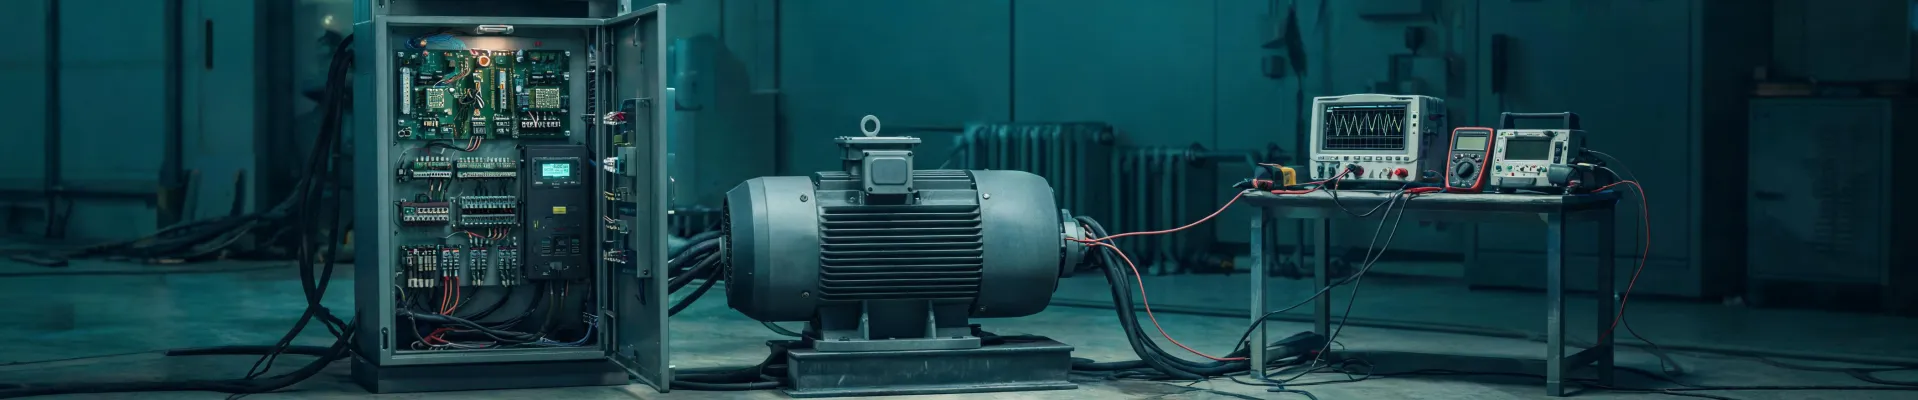
In March 2024, a client called me at around 4:30 on a Friday. They had a Danfoss VFD throwing an alarm code that no one on site had seen before. The line was supposed to restart Monday morning. The previous vendor's support number had changed. The manual was nowhere in the building. They needed a replacement, or a fix, in 36 hours.
I coordinate emergency support for a controls distributor, so I get the calls that come in after everyone else has tried something. We got there, found the issue, and swapped in an identical drive from our shelf. But I remember the call for a different reason: the drive wasn't actually dead. It had been misconfigured during a hasty morning changeover. The real failure was the process around the drive.
That's the thing I've learned after four years and something like 240 emergency calls. A Danfoss VFD emergency is rarely about the VFD.
The Surface Problem: Fault Codes, Dead Drives, and Empty Shelves
At first glance, the emergency is always the same. A fault code. A burned terminal. A drive that won't talk to the PLC. A customer who needs a replacement shipped overnight because their only spare is on another continent.
When you're standing in front of a machine that won't run, you don't want a lecture. You want answers. That's why our team treats danfoss vfd tech support as a triage task: what is the machine doing, what is the drive telling us, how fast can we get a known-good replacement if needed?
But if I look at the last 50 emergency calls we processed, maybe 20% of them involved an actual hardware failure. The rest were wiring, parameters, grounding, or a mismatch between the drive and the motor. The symptom looked sudden. The cause wasn't.
When I say most of these calls are not hardware failures, I do not mean they're easy to solve. They're usually harder, because someone has already changed three things before calling for help.
The Deeper Issue: Why Does It Suddenly Become Urgent?
To understand the pattern, you have to look at what happens before the call. In my experience, three things create most of these 'sudden' failures.
Nobody Owns the Specification
Last fall, we were called to a plant where a 22 kW Danfoss VFD kept tripping on overvoltage during deceleration. The customer thought the brake resistor was bad. It wasn't. The issue started weeks earlier when someone replaced the original braking contactor with whatever was in the maintenance cabinet. The coil voltage and contact ratings looked close enough. They weren't.
This is why contactor specifications matter so much. A contactor's coil voltage, contact rating, and even its pickup voltage can change how the whole motor circuit behaves. 'Close enough' is not a spec. When you source a contactor as a bulk item without cross-checking the datasheet, you're transferring risk to the most expensive part of the system.
The Drive Is Treated As a Commodity
Here's a statement that won't make me popular with some distributors: buying a Danfoss VFD the same way you'd buy a pack of resistors is fine until something goes wrong. Then the purchase price becomes irrelevant and the only thing that matters is whether someone can answer a technical question at 11 p.m.
Danfoss VFD tech support isn't supposed to be an afterthought. It's the part of the product that turns a piece of hardware into a working solution. In one 2025 support case, we watched a customer save $400 on a drive from an online marketplace and then pay $1,100 in emergency troubleshooting when no one could explain the parameter file. The math didn't work.
The Control Layer Was an Afterthought
The third reason so many emergencies start with a VFD but end up in the PLC is that people treat control components as purely transactional. This is where bulk safety PLC and OEM vs private label decisions matter more than most buyers expect.
A safety PLC is not a standard PLC with a safety sticker. It has specific safety ratings like SIL or PL, software versions, and validation requirements. When you buy a bulk safety PLC, you need to know exactly what documentation and support will come with it. A missing manual might be fine for a general-purpose relay. It's not fine for a safety function.
Same thing with the PLC OEM vs private label debate. I understand the appeal of private-label versions: they're often cheaper, and the hardware can be identical. But the firmware versioning and support trail can be completely different. We've seen plants get stuck with a private-label PLC that the original vendor would not support because the serial number didn't match their records. Again, not a hardware failure. A sourcing failure.
The Cost of 'It'll Probably Be Fine'
Here's what bothers me about the 'it'll probably be fine' mindset. The cost of being wrong is not just the replacement drive.
Take the March 2024 call I mentioned. If we hadn't had that exact Danfoss VFD in stock and someone who could get there before Monday, the client's alternative was a $50,000 penalty clause for missing their own delivery contract. That's not hypothetical. That was in their contract.
Last quarter, we tracked 47 rush orders. 95% of them hit their deadline. The other 5%? They all came down to the same thing: someone tried to save a little money or a little time at the decision point, and then had to spend a lot more money and a lot more time correcting it.
I have mixed feelings about emergency support premiums. Part of me thinks they're predatory. Another part remembers the operational chaos that a genuine rush causes—people pulled off other jobs, parts flown overnight, zero margin for error. The premium is real, and it's partly a stress tax.
I'm not immune to the pattern. Once, we skipped the final compatibility check on a 30-drive order because we had done the same setup dozens of times. The client's motor was dual-voltage, and the parameter file had been copied from an old 380V job. Twenty-two drives faulted on startup. It cost us $6,800 in overtime and a very long weekend. After that 30-drive incident, we implemented a 48-hour buffer policy for any critical spare order.
What Actually Helps When the Clock Is Running
So, what do we do differently now? Honestly, it's not that complicated. The most efficient fix is the one that happens before the line stops.
- We ask for the drive model, the parameter file, and the last three configuration changes before we send anyone anywhere. That one question eliminates half of the 'emergencies.'
- We keep common Danfoss VFDs, safety PLCs, and matching contactors in stock in our own facility, where we can verify them against the client's actual specs.
- We treat contactor specifications and bulk safety PLC documentation as part of the spare parts order, not as an optional extra.
- For PLC OEM vs private label, we ask who will support the product in three years. The answer shapes what we recommend.
None of this is high-tech. It's just the unglamorous work of knowing what problem you're actually solving.
At this point, I don't need to see the fault code to know what question to ask. I need the spec sheet, the recent changes, and the story. The next time a Danfoss VFD fault code lights up, look at the drive. Then look at the spec sheet. The drive might be fine. The spec sheet is probably where the truth is hiding.
Rebecca Sloan
Rebecca Sloan is a power distribution and protection analyst specializing in circuit breakers, switchgear, contactors, fuses, surge protective devices, and coordination. She applies IEC 60947-2 breaker requirements, IEC 60269 fuse characteristics, and IEC 61643-11 tests while examining rated voltage, breaking capacity, time-current curves, selectivity, and prospective short-circuit current. She helps engineers and buyers compare protective devices against documented fault levels, installation conditions, maintenance access, and continuity priorities.